From MDPs to general-utility MDPs

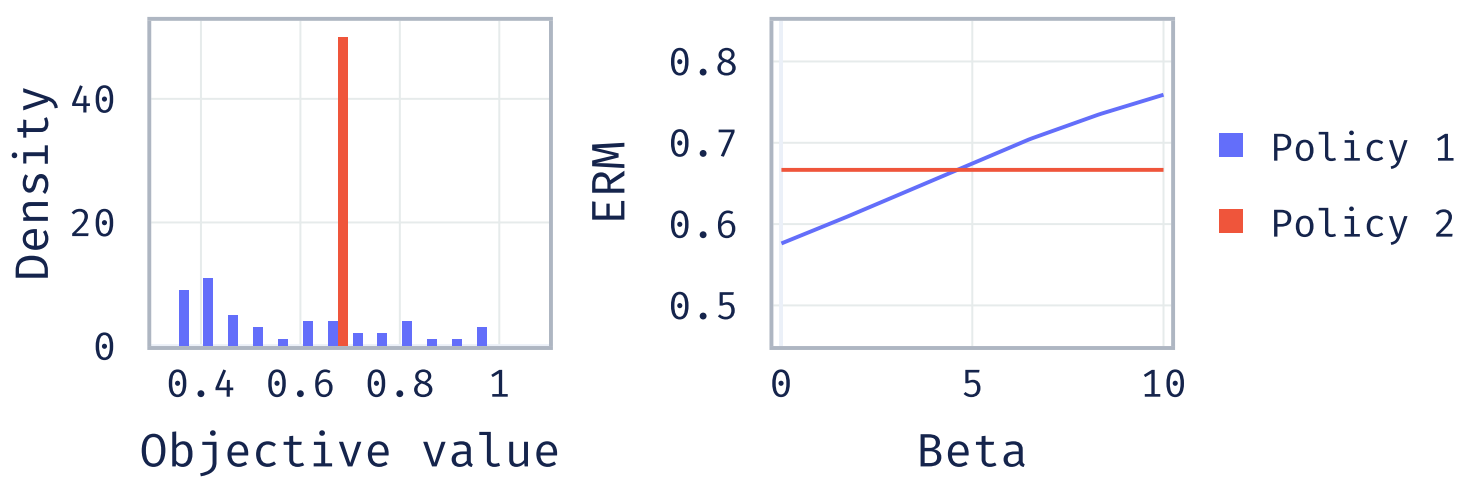
Bringing risk-awareness to general-utility MDPs

We motivate and explore risk-aware general-utility MDPs, where we aim to find an optimal policy with respect to a risk measure of the distribution of objective values induced by its interaction with the MDP.
August 2026 · Pedro P. Santos (based in joint work with Fábio Vital, Alberto Sardinha, and Francisco S. Melo)
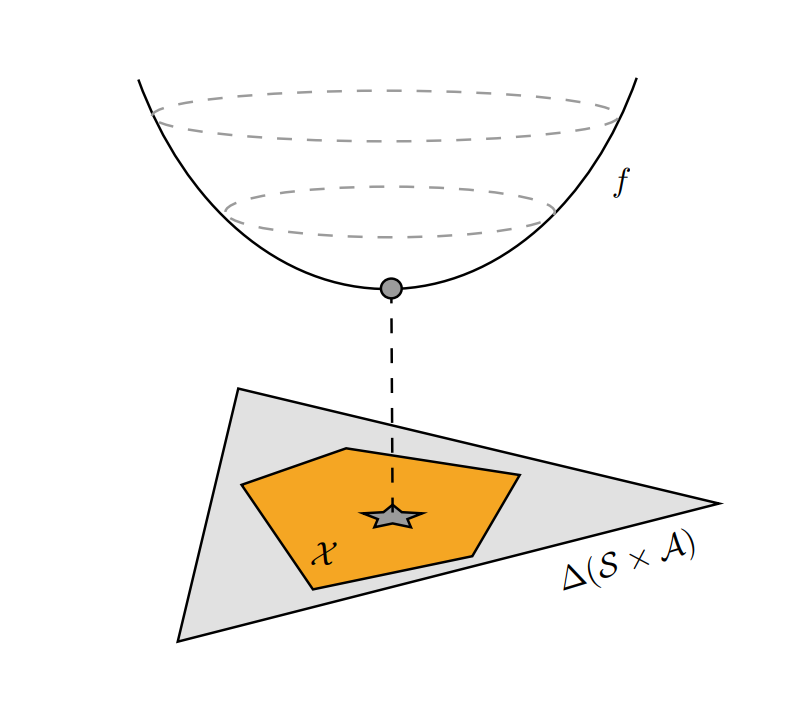
From MDPs to general-utility MDPs

From MDPs to general-utility MDPs

We explore how general-utility Markov decision processes (GUMDPs) can encode a more rich set of objectives than those considered by the framework of MDPs (with stationary cost functions).

August 2026 · Pedro P. Santos
From concentrability coefficients to maximum state entropy exploration

From concentrability coefficients to maximum state entropy exploration

We provide an explanation as to why maximum entropy data distributions are minimax optimal for approximate value iteration algorithms in the face of uncertainty regarding the underlying Markov decision process (MDP). We also investigate connections between such minimax optimal solutions and maximum state entropy exploration methods.

June 2024 · Pedro P. Santos (based in joint work with Diogo S. Carvalho, Alberto Sardinha, and Francisco S. Melo)